Data & Analytics Services
Data Engineering & Pipeline Services
A useful data pipeline needs more than a successful connection. Macrofix develops data engineering services around approved sources, clear transformation rules, validated analytical datasets and operating ownership. We design ingestion and change handling, build the agreed processing paths and test source-to-target results, so teams can understand what the pipeline delivers and how to respond when inputs or dependencies change.
Discuss Your Data Engineering Project
Turn Source Data Into Maintainable Analytical Assets
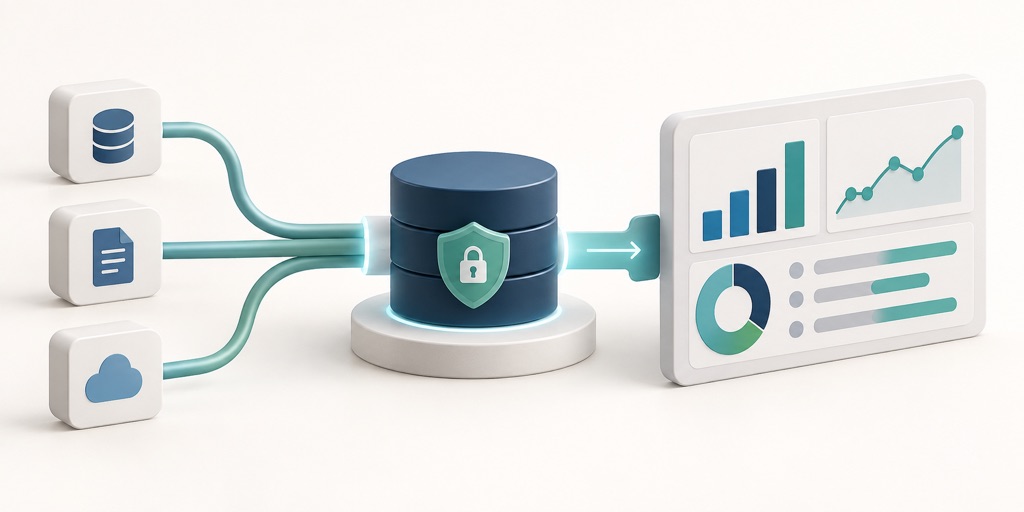
We begin with the target consumers, source behavior and the dataset needed for analysis. Engineering defines how records arrive, how changes and history are handled, and which rules produce the delivered asset. The engagement can build new pipelines, improve existing processing or deliver a bounded platform phase without assuming every source requires the same load pattern.
Architecture choices sit within data platform consulting. Business priorities can be clarified through data strategy services; narrower profiling and cleansing engagements are available through data preparation services.
Data Engineering From Source Assessment to Handover
Choose a pipeline assessment, ingestion and transformation build, analytical dataset delivery or improvement of an existing engineering workflow. We identify sources, targets, environments, data rules, execution boundaries and acceptance evidence. Source-system changes, new platform deployment, streaming, dashboard development and recurring operations are included only when expressly scoped. Unsupported connectors or unavailable source behavior require discovery before a delivery commitment.
Source Assessment and Pipeline Design
We review source interfaces, schemas, identifiers, history, update behavior and the approved access route. Design records the target grain, consumers, load windows and dependencies. We identify assumptions about records, source limits and upstream changes before implementation. Source ownership and permission approval remain with authorized teams; pipeline design is not an instruction to broaden access or alter operational systems without a separate decision.
- Source interfaces, schemas and identifiers
- Record changes, history and source constraints
- Target dataset grain and consumer needs
- Load windows, dependencies and access assumptions
Ingestion and Incremental Load Development
Ingestion development implements the agreed extraction and loading route, with full or incremental behavior selected for the source and target. We define checkpoints, duplicate handling, late arrivals and updates or deletions where required. Source capabilities and permissions determine which patterns are feasible. Change capture is not assumed to be available for every system, and an incremental load does not by itself guarantee complete historical reconstruction.
- Approved extraction and target-loading route
- Full or incremental behavior and checkpoints
- Updates, deletions and late-arriving records where scoped
- Duplicate handling and source-capability validation
Transformations and Analytical Dataset Engineering
Transformations implement approved business and data rules with explicit keys, types, joins, history and output grain. Analytical datasets are structured for the agreed consumers and workload. Microsoft’s modern warehouse architecture example illustrates the separation of source-aligned, transformed and consumption-ready assets. We adapt the design to the actual platform and need rather than require every engagement to implement the same layers or toolchain.
- Approved data and business transformation rules
- Types, keys, joins and output grain
- Required history and analytical dataset structure
- Documented processing assumptions and dependencies
Quality Checks and Source-to-Target Reconciliation
Quality and reconciliation checks compare delivered records and aggregates with agreed source evidence and rules. We review uniqueness, relationships, required values, accepted domains and transformation exceptions where relevant. Failed checks have a defined route to investigation or controlled release decisions. Tests validate their stated conditions; passing a selected suite does not prove every source fact is accurate or replace business acceptance.
Execution Controls and Operating Handover
Execution design records dependencies, load boundaries, retries, recovery and output-publication behavior. Apache Airflow’s best-practice guidance provides one reference for tasks that produce consistent outcomes on rerun. We review side effects and target behavior rather than promise exactly-once execution across all systems. Handover includes run procedures, validation evidence and named owners; recurring monitoring and incident coverage require a separate operating scope.
Agree Your Data Engineering Blueprint
The blueprint identifies sources, extraction routes, targets, schemas, keys and history requirements. It records transformation decisions, quality checks, load and recovery behavior, environments and consumers. We agree acceptance evidence before building the scoped pipeline. Platform provisioning, source remediation, analytical reporting and ongoing operations are separately identified so the delivery boundary remains clear.
- Sources, extraction routes and target assets
- Schemas, identifiers and history requirements
- Transformation rules and dataset consumers
- Quality and reconciliation evidence
- Load, rerun and recovery behavior
- Release environments and operating boundaries
Assign Source, Pipeline and Dataset Owners
Source owners approve extraction routes and explain upstream changes. Data and business owners approve definitions, transformation decisions and acceptance rules. Pipeline and platform owners maintain code, configuration and run procedures; dataset owners manage consumer-facing definitions and changes. Authorized security functions approve access boundaries. Operating coverage and escalation responsibilities are agreed, not inferred from project handover.
- Source owners approve extraction and upstream change information.
- Business and data owners approve definitions and quality rules.
- Pipeline and platform owners maintain assets and run procedures.
- Dataset owners manage consumer definitions and agreed changes.
Our Data Engineering Delivery Process
We assess source behavior and consumer requirements, then document the pipeline and dataset design. Development implements approved ingestion, change handling and transformations. Validation checks normal loads, relevant exceptions and recovery behavior against agreed evidence. Release and handover transfer the scoped assets, documentation and responsibilities, with further sources or operating coverage planned separately.
- Assess source behavior and target consumer requirements.
- Agree pipeline, dataset and validation design.
- Build ingestion, change handling and transformations.
- Test data outputs, exceptions and recovery behavior.
- Release and hand over assets with operating responsibilities.
Validate the Pipeline Before Production Release
Acceptance checks whether the pipeline delivers the agreed data and behaves as designed in the target environment. We review source-to-target reconciliation, identifiers and history, transformation rules, relevant rerun cases and access boundaries. Load limitations, unresolved exceptions and recovery assumptions are documented with owners. A successful connection or one test run is not proof of production readiness for every dataset and failure scenario.
- Source-to-target data reconciles within agreed rules
- Identifiers, history and transformations reviewed
- Relevant load and rerun cases tested
- Exceptions, access and recovery assumptions documented
- Dataset and operating owners accept the handover
Data Engineering Services FAQs
The agreed scope can include source assessment, pipeline design, ingestion, incremental loading, transformations, analytical datasets, quality checks, reconciliation and operating handover. We identify sources, targets and environments in the proposal. Source-system changes, new platforms, streaming, dashboards and recurring operations are separate unless specified.
Data preparation focuses on profiling, cleaning and shaping agreed data for analysis. Data engineering builds and maintains processing paths between sources and target assets, including load behavior, transformations, dependencies and operating handover. The work can overlap, but a preparation task does not automatically establish a production pipeline.
No. Feasibility depends on source interfaces, record identifiers, update and deletion behavior, permissions and target requirements. We assess those conditions before selecting the load pattern. Checkpoints and reconciliation help validate the agreed behavior, but complete change history is not assumed to exist for every source.
Not universally. We review repeatable load boundaries, target writes and side effects so reruns can be handled safely for the agreed pipeline. The result depends on the participating systems and tested design. A retry setting alone does not prevent duplicates, partial output or repeated external actions.
No. Tests validate the specific rules and evidence included in their scope. We review source-to-target reconciliation and relevant exceptions, with business owners approving definitions and acceptance criteria. Unchecked conditions, source errors and unresolved issues remain visible; passing a selected suite is not universal data certification.
Only when explicitly scoped. Project handover can include code and configuration, pipeline documentation, validation records and run procedures. Recurring monitoring, administration and incident coverage require agreed services, coverage, escalation routes and owners. Continuously staffed support is not included by default.
Plan Your Data Engineering Engagement
Tell us which systems supply data, what datasets consumers need and how records change over time. Include existing processing tools, load windows, known quality issues and target environments. We will shape a pipeline assessment or build with explicit source boundaries, transformation decisions, validation evidence and operating handover.